Intro to Gradient's Analysis Environment
At Gradient, we leverage advanced tools and technologies to tackle the complex modeling tasks our projects demand. The Gradient Product Team primarily conducts scripting and analysis using R, a comprehensive open-source statistical software. However, the Gradient analysis environment relies on more than statistical software. The backbone of our analysis environment is supported by robust cloud computing services and version control systems, specifically Amazon Web Services (AWS) and GitHub.
While Gradient Research Managers may not be directly involved in data analysis, it is crucial for them to understand the operational framework of Gradient’s analysis processes. This section aims to outline each primary tool, its role in supporting Gradient’s analytical capabilities, and how Research Managers can effectively engage with these components.
R is a powerful language and environment for statistical computing and graphics. It is instrumental in performing statistical analysis, predictive modeling, and data visualization. R is widely used among statisticians for data analysis and boasts a robust community of active users.
Through R, the Product Team can execute complex statistical analyses and create compelling visualizations, crucial for communicating results and informing data-driven decision-making for our clients.
While not required to perform data analysis themselves, Research Managers should have a basic understanding of R’s capabilities and limitations to facilitate effective communication and project planning with the Product Team.
We typically follow Hadley Wickham’s R for Data Science book to a T when coding, so it’s recommended to read this through.
With collaborative features such as version control integration, R Workbench enhances productivity and collaboration among team members. It allows team members to pick up projects where others have left off with near seamless access to the full suite of Gradient’s analysis tools and package repositories.
As a research manager, you are not expected to do any of your own research, but if you do want to do some work in R you can. Unfortunately, our R Workbench setup has limited seats and for cost-saving purposes, we don’t typically offer this for our research managers. If you feel like you’ll be doing a lot of coding, you can ask Stefan Musch if an account is worthwhile.
Otherwise, you can still access our coding repository locally by downloading R and RStudio. Before you get coding, please read through our Coding in R at Gradient and Coding Principles guides. For any further assistance, reach out to the product team.
AWS provides scalable cloud computing resources, offering a suite of services including computing power, database storage, and content delivery, among others.
AWS is pivotal for hosting our data and applications, providing the computational horsepower needed for running data-intensive models. Its flexibility and scalability support the dynamic requirements of our analytical workloads, enabling efficient processing and analysis of large datasets.
Research Managers need to be aware of how AWS resources are allocated and managed for different projects. Understanding the basics of AWS services, such as EC2 for computing and S3 for storage, will be helpful when playing an intermediary role between data vendors (like YouGov, NORC, etc.) and Gradient’s Product Team.
Amazon EC2 provides scalable computing capacity in the Amazon Web Services (AWS) Cloud. Using EC2, you can launch virtual servers, manage security, storage, and networking, and scale up or down as your requirements change. EC2 offers a wide range of instance types designed to suit different use cases, from applications requiring basic processing power to those that need high-performance computing, memory, or graphical processing.
EC2 enables Gradient to house, run, and manage all of our analysis infrastructure on the cloud without the need for physical hardware, thus optimizing costs, performance, and security. In particular, Gradient leverages EC2 to host all of our internal packages, commonly used packages, R Workbench sessions, and APIs.
As a research manager, you typically won’t be interacting with the EC2 infrastructure, but understanding how it works and what it is, is still essential.
Amazon S3 is an object storage service that offers industry-leading scalability, data availability, security, and performance. Typical use cases include storing and protecting large amounts of data. S3 provides easy-to-use management features so companies can organize data and configure finely-tuned access controls to meet compliance requirements.
S3 enables Gradient to store large amounts of data, including survey data files and modeled results. It allows the Product Team to easily access data and models via cloud computing. As a Research Manager, you may, on occasion, upload, download, and access data files from S3.
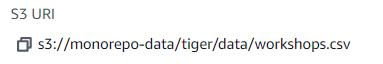
At Gradient, we store all of our project work in its own subfolder within our main data bucket. Most of the time, folder creation will happen automatically when the product team starts working on the analysis, however, sometimes the research manager will need to upload data prior to it being setup. In that case, please create a new folder with the project codename (all lower-case). Store data in a /data folder and share the object url with the product team:
GitHub is a platform for version control and collaboration. It allows multiple team members to work on projects simultaneously, manage changes, and maintain a history of the project’s codebase.
GitHub is essential for code management and collaboration within the Product Team. It facilitates code review, change tracking, and feature integration, ensuring that all team members are aligned and that the project’s codebase is up-to-date and accessible.
While Research Managers may not engage directly with code on GitHub, understanding the platform’s role in project management and version control is important. Familiarity with the basics of GitHub can aid in monitoring project progress, understanding specific analyses that have been conducted in the past, and facilitating communication among team members.
In the survey design phase of every project, make sure you schedule a pre-mortem analysis meeting with the product team. These meetings should focus on discussing potential analysis strategies, expected outcomes, and data requirements. This proactive approach helps in identifying potential challenges and aligning expectations, ensuring a smoother workflow once data collection begins. They also have the added benefit of offering unexpected and novel solutions based on product team member expertise and experience.
Keep regular communication with members of the product team to keep them updated on project progress and any deviations from the plan. Keep product team members updated through Jira issues and other documentation, like the Project Playbook. This documentation should include meeting notes, decisions made, and changes to the project scope or timeline, ensuring all team members are on the same page and can easily track the project history.
When making requests to the product team, be as specific as possible. Clearly outline what is needed, including precise descriptions and any necessary context. Link to relevant documents, previous project documentation, or specific sections in the Project Playbook to provide clear references and minimize misunderstandings or the need for rework. When making requests, make sure to include variable names and anticipated outputs to make the specification as clear as possible.